diff --git a/README.zh-CN.md b/README.zh-CN.md
index 64e6c2c9..0dd667a4 100644
--- a/README.zh-CN.md
+++ b/README.zh-CN.md
@@ -172,7 +172,7 @@ Ultralytics 支持广泛的 YOLO 模型,从早期的版本如 [YOLOv3](https:/
| [YOLO26x-sem](https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26x-sem.pt) | 1024 × 2048 | 83.6 | 48.9 ± 0.2 | 40.2 | 861.7 |
- **mIoUval** 值指的是在 [Cityscapes](https://www.cityscapes-dataset.com/) 验证集上的单模型单尺度性能。
使用 `yolo semantic val data=cityscapes.yaml device=0 imgsz=2048` 复现结果。
-- **速度** 指标是在 RTX3090 实例上对 Cityscapes 验证集图像进行平均测量的。
使用 `yolo semantic val data=cityscapes.yaml batch=1 device=0 imgsz=2048` 复现结果。
+- **速度** 指标是在 RTX3090 实例上对 Cityscapes 验证集图像进行平均测量的。
使用 `yolo semantic val data=cityscapes.yaml batch=1 device=0|cpu imgsz=2048` 复现结果。
@@ -203,7 +203,7 @@ Ultralytics 支持广泛的 YOLO 模型,从早期的版本如 [YOLOv3](https:/
| [YOLO26s-pose](https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26s-pose.pt) | 640 | 63.0 | 86.6 | 85.3 ± 0.9 | 2.7 ± 0.0 | 10.4 | 23.9 |
| [YOLO26m-pose](https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26m-pose.pt) | 640 | 68.8 | 89.6 | 218.0 ± 1.5 | 5.0 ± 0.1 | 21.5 | 73.1 |
| [YOLO26l-pose](https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26l-pose.pt) | 640 | 70.4 | 90.5 | 275.4 ± 2.4 | 6.5 ± 0.1 | 25.9 | 91.3 |
-| [YOLO26x-pose](https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26x-pose.pt) | 640 | 71.7 | 91.6 | 565.4 ± 3.0 | 12.2 ± 0.2 | 57.6 | 201.7 |
+| [YOLO26x-pose](https://github.com/ultralytics/assets/releases/download/v8.4.0/yolo26x-pose.pt) | 640 | 71.6 | 91.6 | 565.4 ± 3.0 | 12.2 ± 0.2 | 57.6 | 201.7 |
- **mAPval** 值指的是在 [COCO Keypoints val2017](https://docs.ultralytics.com/datasets/pose/coco) 数据集上的单模型单尺度性能。详见 [YOLO 性能指标](https://docs.ultralytics.com/guides/yolo-performance-metrics)。
使用 `yolo val pose data=coco-pose.yaml device=0` 复现结果。
- **速度** 指标是在 [Amazon EC2 P4d](https://aws.amazon.com/ec2/instance-types/p4/) 实例上对 COCO val 图像进行平均测量的。CPU 速度使用 [ONNX](https://onnx.ai/) 导出进行测量。GPU 速度使用 [TensorRT](https://developer.nvidia.com/tensorrt) 导出进行测量。
使用 `yolo val pose data=coco-pose.yaml batch=1 device=0|cpu` 复现结果。
diff --git a/docs/en/datasets/classify/imagenet.md b/docs/en/datasets/classify/imagenet.md
index 4ddb23e1..cc25a43d 100644
--- a/docs/en/datasets/classify/imagenet.md
+++ b/docs/en/datasets/classify/imagenet.md
@@ -121,7 +121,7 @@ For more in-depth training instruction, refer to our [Training page](../../modes
### Why should I use the Ultralytics YOLO26 pretrained models for my ImageNet dataset projects?
-Ultralytics YOLO26 pretrained models offer state-of-the-art performance in terms of speed and [accuracy](https://www.ultralytics.com/glossary/accuracy) for various computer vision tasks. For example, the YOLO26n-cls model, with a top-1 accuracy of 70.0% and a top-5 accuracy of 89.4%, is optimized for real-time applications. Pretrained models reduce the computational resources required for training from scratch and accelerate development cycles. Learn more about the performance metrics of YOLO26 models in the [ImageNet Pretrained Models section](#imagenet-pretrained-models).
+Ultralytics YOLO26 pretrained models offer state-of-the-art performance in terms of speed and [accuracy](https://www.ultralytics.com/glossary/accuracy) for various computer vision tasks. For example, the YOLO26n-cls model, with a top-1 accuracy of 71.4% and a top-5 accuracy of 90.1%, is optimized for real-time applications. Pretrained models reduce the computational resources required for training from scratch and accelerate development cycles. Learn more about the performance metrics of YOLO26 models in the [ImageNet Pretrained Models section](#imagenet-pretrained-models).
### How is the ImageNet dataset structured, and why is it important?
diff --git a/docs/en/datasets/classify/index.md b/docs/en/datasets/classify/index.md
index 32f42f5e..2031282a 100644
--- a/docs/en/datasets/classify/index.md
+++ b/docs/en/datasets/classify/index.md
@@ -8,7 +8,7 @@ keywords: YOLO, image classification, dataset structure, CIFAR-10, Ultralytics,
## Dataset Structure for YOLO Classification Tasks
-For [Ultralytics](https://www.ultralytics.com/) YOLO classification tasks, the dataset must be organized in a specific split-directory structure under the `root` directory to facilitate proper training, testing, and optional validation processes. This structure includes separate directories for training (`train`) and testing (`test`) phases, with an optional directory for validation (`val`).
+For [Ultralytics](https://www.ultralytics.com/) YOLO classification tasks, the dataset must be organized in a specific split-directory structure under the `root` directory to facilitate proper training, testing, and optional validation processes. This structure includes separate directories for training (`train`) and validation (`val`) phases, with an optional directory for testing (`test`).
Each of these directories should contain one subdirectory for each class in the dataset. The subdirectories are named after the corresponding class and contain all the images for that class. Ensure that each image file is named uniquely and stored in a common format such as JPEG or PNG.
diff --git a/docs/en/datasets/detect/index.md b/docs/en/datasets/detect/index.md
index ebd97420..43d052df 100644
--- a/docs/en/datasets/detect/index.md
+++ b/docs/en/datasets/detect/index.md
@@ -237,7 +237,7 @@ Here is a list of the supported datasets and a brief description for each:
- [COCO8-Multispectral](coco8-multispectral.md): A 10-channel multispectral version of COCO8 created by interpolating RGB wavelengths, useful for spectral-aware model evaluation.
- [COCO12-Formats](coco12-formats.md): A test dataset with 12 images covering all supported image formats (AVIF, BMP, DNG, HEIC, JP2, JPEG, JPG, MPO, PNG, TIF, TIFF, WebP) for validating image loading pipelines.
- [COCO128](coco128.md): A smaller subset of the first 128 images from COCO train and COCO val, suitable for tests.
-- [Construction-PPE](construction-ppe.md): A dataset featuring construction site workers with labeled safety gear such as helmets, vests, gloves, boots, and goggles, including missing-equipment annotations like no_helmet, no_googles for real-world compliance monitoring.
+- [Construction-PPE](construction-ppe.md): A dataset featuring construction site workers with labeled safety gear such as helmets, vests, gloves, boots, and goggles, including missing-equipment annotations like no_helmet, no_goggle for real-world compliance monitoring.
- [Global Wheat 2020](globalwheat2020.md): A dataset containing images of wheat heads for the Global Wheat Challenge 2020.
- [HomeObjects-3K](homeobjects-3k.md): A dataset of indoor household items including beds, chairs, TVs, and more—ideal for applications in smart home automation, robotics, augmented reality, and room layout analysis.
- [KITTI](kitti.md): A dataset featuring real-world driving scenes with stereo, LiDAR, and GPS/IMU data, used here for **2D object detection** tasks such as identifying cars, pedestrians, and cyclists in urban, rural, and highway environments.
diff --git a/docs/en/datasets/pose/index.md b/docs/en/datasets/pose/index.md
index c16a57a4..f11b52c8 100644
--- a/docs/en/datasets/pose/index.md
+++ b/docs/en/datasets/pose/index.md
@@ -28,7 +28,7 @@ Format with 2D keypoints
...
```
-Format with 3D keypoints (includes visibility per point)
+Format with keypoint visibility (includes visibility per point)
```
@@ -157,7 +157,7 @@ The Ultralytics YOLO format for pose estimation datasets involves labeling each
- Object width and height (normalized)
- Object keypoint coordinates (normalized pxn and pyn)
-For 2D poses, keypoints include pixel coordinates. For 3D, each keypoint also has a visibility flag. For more details, see [Ultralytics YOLO format](#ultralytics-yolo-format).
+For 2D poses, keypoints include normalized x and y coordinates. With a visibility dimension, each keypoint also has a visibility flag. For more details, see [Ultralytics YOLO format](#ultralytics-yolo-format).
### How do I use the COCO-Pose dataset with Ultralytics YOLO?
diff --git a/docs/en/datasets/semantic/index.md b/docs/en/datasets/semantic/index.md
index 8d81770f..3856ca8c 100644
--- a/docs/en/datasets/semantic/index.md
+++ b/docs/en/datasets/semantic/index.md
@@ -21,7 +21,7 @@ Semantic segmentation datasets use one image file and one mask file per sample.
- Pixel values `0`, `1`, `2`, ... represent class IDs from the dataset `names` mapping.
- Pixel value `255` is treated as the ignore label and is excluded from loss and metric computation.
- Mask files should use the same stem as their matching image file, for example `frankfurt_000000_000294.png`.
-- Supported mask extensions are `.png`, `.PNG`, `.bmp`, and `.tif`.
+- Masks are resolved as `.png` by default; if missing, other supported image extensions are also accepted. Use lossless formats such as `.png` or `.tiff`, since lossy compression (e.g. `.jpg`) corrupts the class ID pixel values.
The default layout keeps images and masks in parallel folders. The `masks_dir` value from the dataset YAML replaces the `images` path component to find masks.
diff --git a/docs/en/guides/custom-trainer.md b/docs/en/guides/custom-trainer.md
index 4b77ac82..dd6b4d87 100644
--- a/docs/en/guides/custom-trainer.md
+++ b/docs/en/guides/custom-trainer.md
@@ -187,7 +187,7 @@ model.train(data="coco8.yaml", epochs=10, trainer=WeightedTrainer)
## Saving the Best Model by Custom Metric
-The trainer saves `best.pt` based on fitness, which defaults to `0.9 × mAP@0.5:0.95 + 0.1 × mAP@0.5`. To use a different metric (like `mAP@0.5` or recall), override `validate()` and return your chosen metric as the fitness value. The built-in `save_model()` will then use it automatically:
+The trainer saves `best.pt` based on fitness, which for detection defaults to `mAP@0.5:0.95` (weights `[0.0, 0.0, 0.0, 1.0]` for [P, R, mAP@0.5, mAP@0.5:0.95]). To use a different metric (like `mAP@0.5` or recall), override `validate()` and return your chosen metric as the fitness value. The built-in `save_model()` will then use it automatically:
```python
from ultralytics import YOLO
diff --git a/docs/en/guides/export-non-yolo-models.md b/docs/en/guides/export-non-yolo-models.md
index 6ddb7937..5e96c79f 100644
--- a/docs/en/guides/export-non-yolo-models.md
+++ b/docs/en/guides/export-non-yolo-models.md
@@ -127,7 +127,7 @@ import coremltools as ct
from ultralytics.utils.export import torch2coreml
inputs = [ct.TensorType("input", shape=(1, 3, 224, 224))]
-ct_model = torch2coreml(model, inputs, im, output_file="resnet18.mlpackage")
+ct_model = torch2coreml(model, inputs, im, classifier_names=None, output_file="resnet18.mlpackage")
```
For [classification](https://www.ultralytics.com/glossary/image-classification) models, pass a list of class names to `classifier_names` to add a classification head to the CoreML model.
diff --git a/docs/en/guides/kfold-cross-validation.md b/docs/en/guides/kfold-cross-validation.md
index 1f9d3291..4688657c 100644
--- a/docs/en/guides/kfold-cross-validation.md
+++ b/docs/en/guides/kfold-cross-validation.md
@@ -270,7 +270,7 @@ fold_lbl_distrb.to_csv(save_path / "kfold_label_distribution.csv")
) # include any additional train arguments
```
-3. You can also use [Ultralytics data.utils.autosplit](https://docs.ultralytics.com/reference/data/utils) function for automatic dataset splitting:
+3. You can also use [Ultralytics data.split.autosplit](https://docs.ultralytics.com/reference/data/split) function for automatic dataset splitting:
```python
from ultralytics.data.split import autosplit
diff --git a/docs/en/guides/model-deployment-options.md b/docs/en/guides/model-deployment-options.md
index 32eb578c..135c4b51 100644
--- a/docs/en/guides/model-deployment-options.md
+++ b/docs/en/guides/model-deployment-options.md
@@ -306,7 +306,7 @@ Yes, YOLO26 models can be deployed on mobile devices using [TensorFlow](https://
```bash
# CLI command for TFLite export
- yolo export --format tflite
+ yolo export model=yolo26n.pt format=tflite
```
For more details on deploying models to mobile, refer to our [TF Lite integration guide](../integrations/tflite.md).
diff --git a/docs/en/guides/model-training-tips.md b/docs/en/guides/model-training-tips.md
index 9d1f4166..2baccb8e 100644
--- a/docs/en/guides/model-training-tips.md
+++ b/docs/en/guides/model-training-tips.md
@@ -57,7 +57,7 @@ Using the maximum batch size supported by your GPU, you can fully take advantage
Watch: How to Use Batch Inference with Ultralytics YOLO26 | Speed Up Object Detection in Python 🎉
-With respect to YOLO26, you can set the `batch_size` parameter in the [training configuration](../modes/train.md) to match your GPU capacity. Also, setting `batch=-1` in your training script will automatically determine the [batch size](https://www.ultralytics.com/glossary/batch-size) that can be efficiently processed based on your device's capabilities. By fine-tuning the batch size, you can make the most of your GPU resources and improve the overall training process.
+With respect to YOLO26, you can set the `batch` parameter in the [training configuration](../modes/train.md) to match your GPU capacity. Also, setting `batch=-1` in your training script will automatically determine the [batch size](https://www.ultralytics.com/glossary/batch-size) that can be efficiently processed based on your device's capabilities. By fine-tuning the batch size, you can make the most of your GPU resources and improve the overall training process.
### Subset Training
diff --git a/docs/en/guides/model-yaml-config.md b/docs/en/guides/model-yaml-config.md
index f0b0d053..e7633e04 100644
--- a/docs/en/guides/model-yaml-config.md
+++ b/docs/en/guides/model-yaml-config.md
@@ -134,7 +134,7 @@ Modules are organized by functionality and defined in the [Ultralytics modules d
| ------------- | --------------------------------- | ------------------------------------------------------------------------------------------------ | -------------------------------------------------------- |
| `TorchVision` | Load any torchvision model | [block.py](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/nn/modules/block.py) | `[out_ch, model_name, weights, unwrap, truncate, split]` |
| `Index` | Extract specific tensor from list | [block.py](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/nn/modules/block.py) | `[out_ch, index]` |
-| `Detect` | YOLO detection head | [head.py](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/nn/modules/head.py) | `[nc, anchors, ch]` |
+| `Detect` | YOLO detection head | [head.py](https://github.com/ultralytics/ultralytics/blob/main/ultralytics/nn/modules/head.py) | `[nc]` |
!!! info "Complete Module List"
@@ -202,11 +202,17 @@ Ultralytics uses a three-tier system in [`parse_model`](https://github.com/ultra
```python
# Core resolution logic
-m = getattr(torch.nn, m[3:]) if "nn." in m else getattr(torchvision.ops, m[4:]) if "ops." in m else globals()[m]
+m = (
+ getattr(torch.nn, m[3:])
+ if "nn." in m
+ else getattr(torchvision.ops, m[16:])
+ if "torchvision.ops." in m
+ else globals()[m]
+)
```
1. **PyTorch modules**: Names starting with `'nn.'` → `torch.nn` namespace
-2. **TorchVision operations**: Names starting with `'ops.'` → `torchvision.ops` namespace
+2. **TorchVision operations**: Names starting with `'torchvision.ops.'` → `torchvision.ops` namespace
3. **Ultralytics modules**: All other names → global namespace via imports
### Module Import Chain
diff --git a/docs/en/guides/object-cropping.md b/docs/en/guides/object-cropping.md
index 529562e0..43b81434 100644
--- a/docs/en/guides/object-cropping.md
+++ b/docs/en/guides/object-cropping.md
@@ -84,7 +84,7 @@ Object cropping with [Ultralytics YOLO26](https://github.com/ultralytics/ultraly
cv2.destroyAllWindows() # destroy all opened windows
```
- When you provide the optional `crop_dir` argument, every cropped object is written to that folder with filenames that include the source image name and class. This makes it easy to inspect detections or build downstream datasets without writing extra code.
+ When you provide the optional `crop_dir` argument, every cropped object is written to that folder with sequentially numbered filenames (e.g. `crop_1.jpg`, `crop_2.jpg`). This makes it easy to inspect detections or build downstream datasets without writing extra code.
### `ObjectCropper` Arguments
diff --git a/docs/en/guides/yolo-thread-safe-inference.md b/docs/en/guides/yolo-thread-safe-inference.md
index b7e7529c..3c4314b9 100644
--- a/docs/en/guides/yolo-thread-safe-inference.md
+++ b/docs/en/guides/yolo-thread-safe-inference.md
@@ -31,7 +31,7 @@ While this sounds like a limitation, threads can still provide concurrency, espe
## The Danger of Shared Model Instances
-Instantiating a YOLO model outside your threads and sharing this instance across multiple threads can lead to [race conditions](https://www.ultralytics.com/glossary/algorithmic-bias), where the internal state of the model is inconsistently modified due to concurrent accesses. This is particularly problematic when the model or its components hold state that is not designed to be thread-safe.
+Instantiating a YOLO model outside your threads and sharing this instance across multiple threads can lead to race conditions, where the internal state of the model is inconsistently modified due to concurrent accesses. This is particularly problematic when the model or its components hold state that is not designed to be thread-safe.
### Non-Thread-Safe Example: Single Model Instance
diff --git a/docs/en/integrations/deepx.md b/docs/en/integrations/deepx.md
index 295ec5e8..fdaa83e6 100644
--- a/docs/en/integrations/deepx.md
+++ b/docs/en/integrations/deepx.md
@@ -135,14 +135,14 @@ The DEEPX format supports the [Export](../modes/export.md), [Predict](../modes/p
### Export Arguments
-| Argument | Type | Default | Description |
-| :--------- | :--------------- | :--------------- | :------------------------------------------------------------------------------------------------------------------------------------------------- |
-| `format` | `str` | `'deepx'` | Target format for the exported model, defining compatibility with DEEPX NPU hardware. |
-| `imgsz` | `int` or `tuple` | `640` | Desired image size for the model input. DEEPX export requires a square input — pass an integer (e.g., `640`) or a tuple where height equals width. |
-| `int8` | `bool` | `True` | Enables INT8 quantization. Required for DEEPX export — automatically set to `True` if not specified. |
-| `data` | `str` | `'coco128.yaml'` | Dataset configuration file used for INT8 calibration. Specifies the calibration image source. |
-| `device` | `str` | `None` | Specifies the device for exporting: GPU (`device=0`) or CPU (`device=cpu`). |
-| `optimize` | `bool` | `False` | Enables higher compiler optimization which reduces inference latency and increases compilation time. |
+| Argument | Type | Default | Description |
+| :--------- | :--------------- | :------------- | :------------------------------------------------------------------------------------------------------------------------------------------------- |
+| `format` | `str` | `'deepx'` | Target format for the exported model, defining compatibility with DEEPX NPU hardware. |
+| `imgsz` | `int` or `tuple` | `640` | Desired image size for the model input. DEEPX export requires a square input — pass an integer (e.g., `640`) or a tuple where height equals width. |
+| `int8` | `bool` | `True` | Enables INT8 quantization. Required for DEEPX export — automatically set to `True` if not specified. |
+| `data` | `str` | `'coco8.yaml'` | Dataset configuration file used for INT8 calibration. Specifies the calibration image source. |
+| `device` | `str` | `None` | Specifies the device for exporting: GPU (`device=0`) or CPU (`device=cpu`). |
+| `optimize` | `bool` | `False` | Enables higher compiler optimization which reduces inference latency and increases compilation time. |
!!! tip
@@ -360,7 +360,7 @@ Yes. Any model trained using [Ultralytics Train Mode](../modes/train.md) and exp
### How many calibration images should I use for DEEPX export?
-The DEEPX export pipeline uses every image in the calibration dataset (after `fraction` filtering) with the EMA calibration method. A few hundred images is usually sufficient for good quantization accuracy. Point `data` at a smaller dataset (or set `fraction` below `1.0`) if compilation time becomes a concern on large datasets.
+The DEEPX export pipeline uses every image in the calibration dataset with the EMA calibration method. A few hundred images is usually sufficient for good quantization accuracy. Point `data` at a smaller dataset if compilation time becomes a concern on large datasets.
### How do I install the DEEPX runtime for inference?
diff --git a/docs/en/integrations/executorch.md b/docs/en/integrations/executorch.md
index 602afebd..5958a0f3 100644
--- a/docs/en/integrations/executorch.md
+++ b/docs/en/integrations/executorch.md
@@ -346,7 +346,7 @@ Note: The `executorch` package ships prebuilt wheels (with the XNNPACK backend),
### Can I run inference with ExecuTorch models directly in Python?
-ExecuTorch models (`.pte` files) are designed for deployment on mobile and edge devices using the ExecuTorch runtime. They cannot be directly loaded with `YOLO()` for inference in Python. You need to integrate them into your target application using the ExecuTorch runtime libraries.
+ExecuTorch models can be loaded directly with `YOLO()` for inference and validation in Python (see the Predict/Validate examples above), and they can also be deployed on mobile and edge devices using the ExecuTorch runtime libraries.
### What platforms are supported by ExecuTorch?
diff --git a/docs/en/integrations/vscode.md b/docs/en/integrations/vscode.md
index cb88048d..cbba9a44 100644
--- a/docs/en/integrations/vscode.md
+++ b/docs/en/integrations/vscode.md
@@ -188,7 +188,7 @@ There are over 💯 keyword arguments for all the various Ultralytics [tasks](..
```python
model.predict(
source=src, # (str, optional) source directory for images or videos
- imgsz=640, # (int | list) input images size as int or list[w,h] for predict
+ imgsz=640, # (int | list) input images size as int or list[h,w] for predict
conf=0.25, # (float) minimum confidence threshold
iou=0.7, # (float) intersection over union (IoU) threshold for NMS
vid_stride=1, # (int) video frame-rate stride
@@ -240,7 +240,7 @@ If you use VS Code and have started to see a message prompting you to install th
1. Install Ultralytics-snippets and the message will no longer be shown 😆!
-2. You can be using `yolo settings vscode_msg False` to disable the message from showing without having to install the extension. You can learn more about the [Ultralytics Settings](../quickstart.md#ultralytics-settings) on the [quickstart](../quickstart.md) page if you're unfamiliar.
+2. You can use `yolo settings vscode_msg=False` to disable the message from showing without having to install the extension. You can learn more about the [Ultralytics Settings](../quickstart.md#ultralytics-settings) on the [quickstart](../quickstart.md) page if you're unfamiliar.
### I have an idea for a new Ultralytics code snippet, how can I get one added?
diff --git a/docs/en/models/fast-sam.md b/docs/en/models/fast-sam.md
index 9aa1a65a..a19d0d23 100644
--- a/docs/en/models/fast-sam.md
+++ b/docs/en/models/fast-sam.md
@@ -192,7 +192,7 @@ Validation of the model on a dataset can be done as follows:
```bash
# Load a FastSAM model and validate it on the COCO8 example dataset at image size 640
- yolo segment val model=FastSAM-s.pt data=coco8.yaml imgsz=640
+ yolo segment val model=FastSAM-s.pt data=coco8-seg.yaml imgsz=640
```
Please note that FastSAM only supports detection and segmentation of a single class of object. This means it will recognize and segment all objects as the same class. Therefore, when preparing the dataset, you need to convert all object category IDs to 0.
@@ -223,7 +223,7 @@ To perform object tracking on an image, use the `track` method as shown below:
## FastSAM official Usage
-FastSAM is also available directly from the [https://github.com/CASIA-IVA-Lab/FastSAM](https://github.com/CASIA-LMC-Lab/FastSAM) repository. Here is a brief overview of the typical steps you might take to use FastSAM:
+FastSAM is also available directly from the [https://github.com/CASIA-IVA-Lab/FastSAM](https://github.com/CASIA-IVA-Lab/FastSAM) repository. Here is a brief overview of the typical steps you might take to use FastSAM:
### Installation
@@ -301,7 +301,7 @@ We would like to acknowledge the FastSAM authors for their significant contribut
}
```
-The original FastSAM paper can be found on [arXiv](https://arxiv.org/abs/2306.12156). The authors have made their work publicly available, and the codebase can be accessed on [GitHub](https://github.com/CASIA-LMC-Lab/FastSAM). We appreciate their efforts in advancing the field and making their work accessible to the broader community.
+The original FastSAM paper can be found on [arXiv](https://arxiv.org/abs/2306.12156). The authors have made their work publicly available, and the codebase can be accessed on [GitHub](https://github.com/CASIA-IVA-Lab/FastSAM). We appreciate their efforts in advancing the field and making their work accessible to the broader community.
## FAQ
diff --git a/docs/en/models/mobile-sam.md b/docs/en/models/mobile-sam.md
index 23acd2b7..178be436 100644
--- a/docs/en/models/mobile-sam.md
+++ b/docs/en/models/mobile-sam.md
@@ -159,17 +159,11 @@ Download the MobileSAM pretrained weights from [Ultralytics assets](https://gith
# Load the model
model = SAM("mobile_sam.pt")
- # Predict a segment based on a single point prompt
- model.predict("ultralytics/assets/zidane.jpg", points=[900, 370], labels=[1])
+ # Predict a segment based on a single box prompt
+ model.predict("ultralytics/assets/zidane.jpg", bboxes=[439, 437, 524, 709])
- # Predict multiple segments based on multiple points prompt
- model.predict("ultralytics/assets/zidane.jpg", points=[[400, 370], [900, 370]], labels=[1, 1])
-
- # Predict a segment based on multiple points prompt per object
- model.predict("ultralytics/assets/zidane.jpg", points=[[[400, 370], [900, 370]]], labels=[[1, 1]])
-
- # Predict a segment using both positive and negative prompts.
- model.predict("ultralytics/assets/zidane.jpg", points=[[[400, 370], [900, 370]]], labels=[[1, 0]])
+ # Predict multiple segments based on multiple box prompts
+ model.predict("ultralytics/assets/zidane.jpg", bboxes=[[439, 437, 524, 709], [114, 196, 313, 708]])
```
Both `MobileSAM` and `SAM` share the same API. For more usage details, see the [SAM documentation](sam.md).
diff --git a/docs/en/models/sam.md b/docs/en/models/sam.md
index 57504cdb..100630cb 100644
--- a/docs/en/models/sam.md
+++ b/docs/en/models/sam.md
@@ -116,6 +116,8 @@ The Segment Anything Model can be employed for a multitude of downstream tasks t
=== "Prompt inference"
```python
+ import cv2
+
from ultralytics.models.sam import Predictor as SAMPredictor
# Create SAMPredictor
@@ -273,7 +275,7 @@ model("ultralytics/assets/zidane.jpg", bboxes=[439, 437, 524, 709])
model("ultralytics/assets/zidane.jpg", points=[900, 370], labels=[1])
# Segment with multiple points prompt
-model("ultralytics/assets/zidane.jpg", points=[[400, 370], [900, 370]], labels=[[1, 1]])
+model("ultralytics/assets/zidane.jpg", points=[[400, 370], [900, 370]], labels=[1, 1])
# Segment with multiple points prompt per object
model("ultralytics/assets/zidane.jpg", points=[[[400, 370], [900, 370]]], labels=[[1, 1]])
diff --git a/docs/en/modes/benchmark.md b/docs/en/modes/benchmark.md
index a4af4743..56246ab8 100644
--- a/docs/en/modes/benchmark.md
+++ b/docs/en/modes/benchmark.md
@@ -102,10 +102,10 @@ Arguments such as `model`, `data`, `imgsz`, `half`, `device`, `verbose` and `for
| --------- | ------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `model` | `None` | Specifies the path to the model file. Accepts both `.pt` and `.yaml` formats, e.g., `"yolo26n.pt"` for pretrained models or configuration files. |
| `data` | `None` | Path to a YAML file defining the dataset for benchmarking, typically including paths and settings for [validation data](https://www.ultralytics.com/glossary/validation-data). Example: `"coco8.yaml"`. |
-| `imgsz` | `640` | The input image size for the model. Can be a single integer for square images or a tuple `(width, height)` for non-square, e.g., `(640, 480)`. |
+| `imgsz` | `640` | The input image size for the model. Must be a single integer for square images (e.g., `640`); `benchmark()` only supports square image sizes. |
| `half` | `False` | Enables FP16 (half-precision) inference, reducing memory usage and possibly increasing speed on compatible hardware. Use `half=True` to enable. |
| `int8` | `False` | Activates INT8 quantization for further optimized performance on supported devices, especially useful for edge devices. Set `int8=True` to use. |
-| `device` | `None` | Defines the computation device(s) for benchmarking, such as `"cpu"` or `"cuda:0"`. |
+| `device` | `'cpu'` | Defines the computation device(s) for benchmarking, such as `"cpu"` or `"cuda:0"`. |
| `verbose` | `False` | Controls the level of detail in logging output. Set `verbose=True` for detailed logs. |
| `format` | `''` | Benchmarks only the specified export format (e.g., `format=onnx`). Leave it blank to test every supported format automatically. |
diff --git a/docs/en/platform/explore.md b/docs/en/platform/explore.md
index 3c9401f3..6874f1dd 100644
--- a/docs/en/platform/explore.md
+++ b/docs/en/platform/explore.md
@@ -197,12 +197,12 @@ See [Projects](train/projects.md) for organizing models in your project.
Official `@ultralytics` content is pinned to the top of the Explore page. This includes:
-| Project | Description | Models | Tasks |
-| --------------------------------- | --------------------------- | ------------------------------ | ---------------------------------------------- |
-| **[YOLO26](../models/yolo26.md)** | Latest January 2026 release | 30 models (5 sizes × 6 tasks) | detect, segment, semantic, pose, OBB, classify |
-| **[YOLO11](../models/yolo11.md)** | Current stable release | 25 models (5 sizes × 5 tasks) | detect, segment, pose, OBB, classify |
-| **YOLOv8** | Previous generation | 20+ models (5 sizes × 4 tasks) | detect, segment, pose, classify |
-| **YOLOv5** | Legacy, widely adopted | 15+ models | detect, segment, classify |
+| Project | Description | Models | Tasks |
+| --------------------------------- | --------------------------- | ----------------------------- | ---------------------------------------------- |
+| **[YOLO26](../models/yolo26.md)** | Latest January 2026 release | 30 models (5 sizes × 6 tasks) | detect, segment, semantic, pose, OBB, classify |
+| **[YOLO11](../models/yolo11.md)** | Current stable release | 25 models (5 sizes × 5 tasks) | detect, segment, pose, OBB, classify |
+| **YOLOv8** | Previous generation | 25 models (5 sizes × 5 tasks) | detect, segment, pose, OBB, classify |
+| **YOLOv5** | Legacy, widely adopted | 15+ models | detect, segment, classify |
Official datasets include benchmark datasets like [coco8](../datasets/detect/coco8.md) (8-image COCO subset), [VOC](../datasets/detect/voc.md), [african-wildlife](../datasets/detect/african-wildlife.md), [dota8](../datasets/obb/dota8.md), and other commonly used computer vision datasets.
diff --git a/docs/en/quickstart.md b/docs/en/quickstart.md
index 97945bde..24aeb4e2 100644
--- a/docs/en/quickstart.md
+++ b/docs/en/quickstart.md
@@ -438,7 +438,7 @@ The table below overviews the adjustable settings within Ultralytics, including
| Name | Example Value | Data Type | Description |
| ------------------ | --------------------- | --------- | ---------------------------------------------------------------------------------------------------------------- |
-| `settings_version` | `'0.0.4'` | `str` | Ultralytics _settings_ version (distinct from the Ultralytics [pip] version) |
+| `settings_version` | `'0.0.6'` | `str` | Ultralytics _settings_ version (distinct from the Ultralytics [pip] version) |
| `datasets_dir` | `'/path/to/datasets'` | `str` | Directory where datasets are stored |
| `weights_dir` | `'/path/to/weights'` | `str` | Directory where model weights are stored |
| `runs_dir` | `'/path/to/runs'` | `str` | Directory where experiment runs are stored |
@@ -452,8 +452,8 @@ The table below overviews the adjustable settings within Ultralytics, including
| `mlflow` | `True` | `bool` | Option to use [MLFlow] for experiment tracking |
| `neptune` | `True` | `bool` | Option to use [Neptune] for experiment tracking |
| `raytune` | `True` | `bool` | Option to use [Ray Tune] for [hyperparameter tuning](https://www.ultralytics.com/glossary/hyperparameter-tuning) |
-| `tensorboard` | `True` | `bool` | Option to use [TensorBoard] for visualization |
-| `wandb` | `True` | `bool` | Option to use [Weights & Biases] logging |
+| `tensorboard` | `False` | `bool` | Option to use [TensorBoard] for visualization |
+| `wandb` | `False` | `bool` | Option to use [Weights & Biases] logging |
| `vscode_msg` | `True` | `bool` | When a VS Code terminal is detected, enables a prompt to download the [Ultralytics-Snippets] extension. |
Revisit these settings as you progress through projects or experiments to ensure optimal configuration.
diff --git a/docs/en/solutions/index.md b/docs/en/solutions/index.md
index ce9f39be..76694db5 100644
--- a/docs/en/solutions/index.md
+++ b/docs/en/solutions/index.md
@@ -148,7 +148,7 @@ For more details, refer to the [`SolutionResults` class documentation](https://d
yolo SOLUTIONS SOLUTION_NAME ARGS
- **SOLUTIONS** is a required keyword.
- - **SOLUTION_NAME** is one of: `['count', 'crop', 'blur', 'workout', 'heatmap', 'isegment', 'queue', 'speed', 'analytics', 'trackzone', 'inference', 'visioneye']`.
+ - **SOLUTION_NAME** is one of: `['count', 'crop', 'blur', 'workout', 'heatmap', 'isegment', 'queue', 'speed', 'analytics', 'trackzone', 'inference', 'visioneye', 'region', 'security', 'parking']`.
- **ARGS** (optional) are custom `arg=value` pairs, such as `show_in=True`, to override default settings.
```bash
diff --git a/docs/en/usage/simple-utilities.md b/docs/en/usage/simple-utilities.md
index 4784876f..49775b93 100644
--- a/docs/en/usage/simple-utilities.md
+++ b/docs/en/usage/simple-utilities.md
@@ -210,7 +210,7 @@ See the [Reference page](../reference/data/split.md#ultralytics.data.split.autos
### Segment-polygon to Binary Mask
-Convert a single polygon (as a list) to a binary mask of the specified image size. The polygon should be in the form of `[N, 2]`, where `N` is the number of `(x, y)` points defining the polygon contour.
+Convert a single polygon (as a list) to a binary mask of the specified image size. The polygon should be a flat 1D array of `N` coordinates listing alternating `x, y` values defining the polygon contour.
!!! warning
@@ -698,7 +698,7 @@ print(VID_FORMATS)
### Make Divisible
-Calculate the nearest whole number to `x` that is evenly divisible by `y`.
+Calculate the smallest whole number greater than or equal to `x` that is evenly divisible by `y`.
```python
from ultralytics.utils.ops import make_divisible
diff --git a/docs/en/yolov5/environments/docker_image_quickstart_tutorial.md b/docs/en/yolov5/environments/docker_image_quickstart_tutorial.md
index 7564c737..77696931 100644
--- a/docs/en/yolov5/environments/docker_image_quickstart_tutorial.md
+++ b/docs/en/yolov5/environments/docker_image_quickstart_tutorial.md
@@ -145,7 +145,7 @@ To run an interactive container instance using only the CPU, use the `-it` flag.
```bash
# Run an interactive container instance using CPU
-sudo docker run -it --runtime=nvidia --ipc=host $t
+sudo docker run -it --ipc=host $t
```
### Using GPU
diff --git a/docs/en/yolov5/tutorials/hyperparameter_evolution.md b/docs/en/yolov5/tutorials/hyperparameter_evolution.md
index b176a260..84b253c3 100644
--- a/docs/en/yolov5/tutorials/hyperparameter_evolution.md
+++ b/docs/en/yolov5/tutorials/hyperparameter_evolution.md
@@ -113,7 +113,7 @@ done
The default evolution settings will run the base scenario 300 times, i.e. for 300 generations. You can modify generations via the `--evolve` argument, i.e. `python train.py --evolve 1000`.
-The main genetic operators are **crossover** and **mutation**. In this work mutation is used, with an 80% probability and a 0.04 variance to create new offspring based on a combination of the best parents from all previous generations. Results are logged to `runs/evolve/exp/evolve.csv`, and the highest fitness offspring is saved every generation as `runs/evolve/hyp_evolved.yaml`:
+The main genetic operators are **crossover** and **mutation**. In this work mutation is used, with an 80% probability and a 0.04 variance to create new offspring based on a combination of the best parents from all previous generations. Results are logged to `runs/evolve/exp/evolve.csv`, and the highest fitness offspring is saved every generation as `runs/evolve/exp/hyp_evolve.yaml`:
```yaml
# YOLOv5 Hyperparameter Evolution Results
@@ -155,7 +155,7 @@ copy_paste: 0.0 # segment copy-paste (probability)
We recommend a minimum of 300 generations of evolution for best results. Note that **evolution is generally expensive and time-consuming**, as the base scenario is trained hundreds of times, possibly requiring hundreds or thousands of GPU hours.
-When evolution finishes, reuse the discovered settings by pointing training at the saved file, for example `python train.py --hyp runs/evolve/hyp_evolved.yaml --data your.yaml --weights yolov5s.pt`.
+When evolution finishes, reuse the discovered settings by pointing training at the saved file, for example `python train.py --hyp runs/evolve/exp/hyp_evolve.yaml --data your.yaml --weights yolov5s.pt`.
## 4. Visualize
diff --git a/docs/en/yolov5/tutorials/multi_gpu_training.md b/docs/en/yolov5/tutorials/multi_gpu_training.md
index fdbccdee..7e40e1c0 100644
--- a/docs/en/yolov5/tutorials/multi_gpu_training.md
+++ b/docs/en/yolov5/tutorials/multi_gpu_training.md
@@ -28,7 +28,7 @@ pip install -r requirements.txt # install
## Training
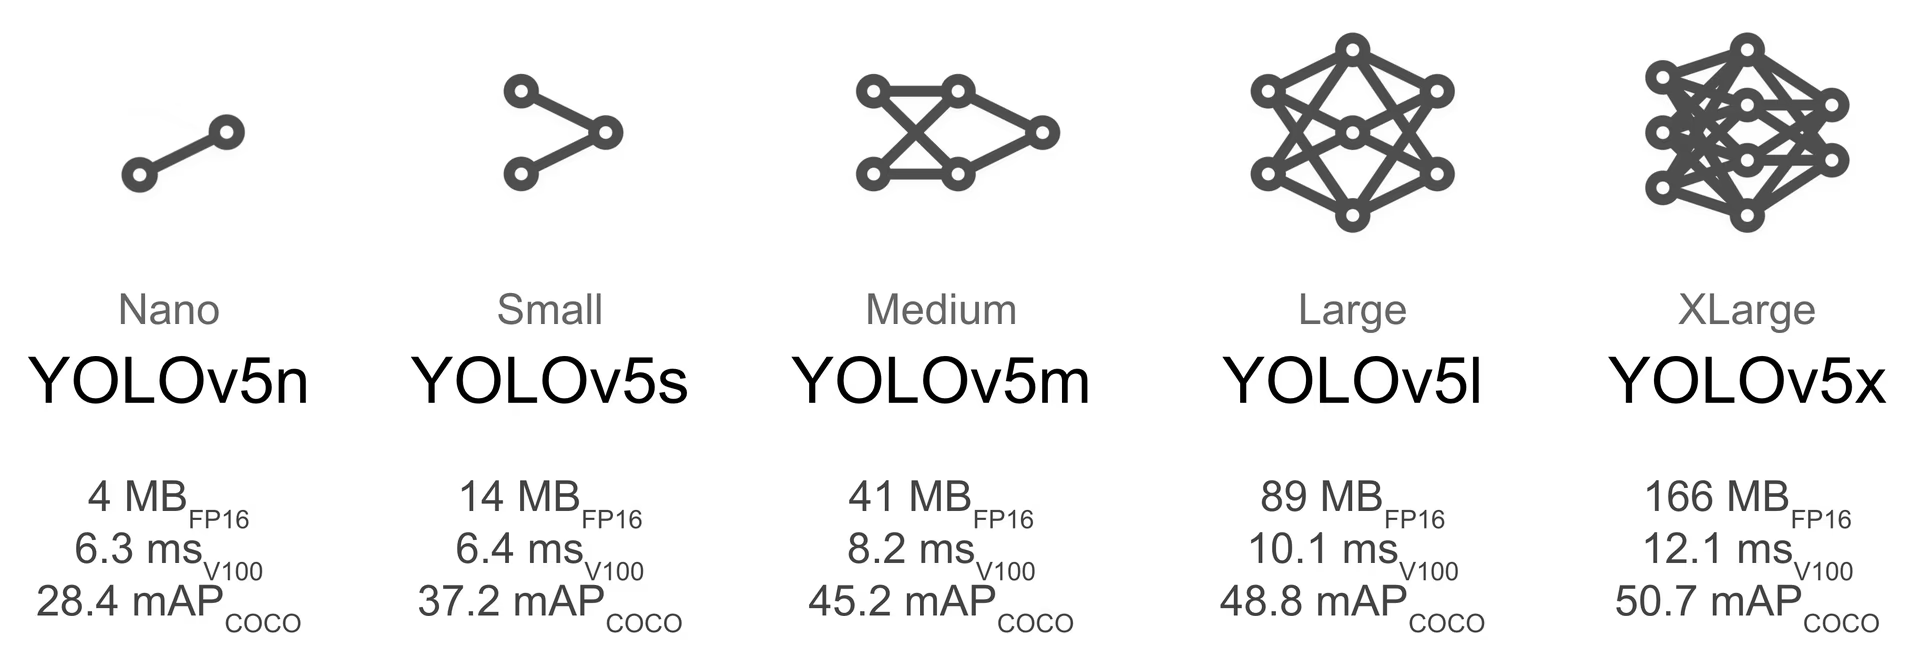
-Select a pretrained model to start training from. Here we select [YOLOv5s](https://github.com/ultralytics/yolov5/blob/master/models/yolov5s.yaml), the smallest and fastest model available. See our README [table](https://github.com/ultralytics/yolov5#pretrained-checkpoints) for a full comparison of all models. We will train this model with Multi-GPU on the [COCO](https://github.com/ultralytics/yolov5/blob/master/data/scripts/get_coco.sh) dataset.
+Select a pretrained model to start training from. Here we select [YOLOv5s](https://github.com/ultralytics/yolov5/blob/master/models/yolov5s.yaml), a small and fast model. See our README [table](https://github.com/ultralytics/yolov5#pretrained-checkpoints) for a full comparison of all models. We will train this model with Multi-GPU on the [COCO](https://github.com/ultralytics/yolov5/blob/master/data/scripts/get_coco.sh) dataset.
diff --git a/docs/en/yolov5/tutorials/tips_for_best_training_results.md b/docs/en/yolov5/tutorials/tips_for_best_training_results.md
index ed01ef21..0fafc6d0 100644
--- a/docs/en/yolov5/tutorials/tips_for_best_training_results.md
+++ b/docs/en/yolov5/tutorials/tips_for_best_training_results.md
@@ -60,9 +60,9 @@ Before modifying anything, **first train with default settings to establish a pe
- **Image size.** COCO trains at native resolution of `--img 640`, though due to the high amount of small objects in the dataset it can benefit from training at higher resolutions such as `--img 1280`. If there are many small objects then custom datasets will benefit from training at native or higher resolution. Best inference results are obtained at the same `--img` as the training was run at, i.e. if you train at `--img 1280` you should also test and detect at `--img 1280`.
- **[Batch size](https://www.ultralytics.com/glossary/batch-size).** Use the largest `--batch-size` that your hardware allows for. Small batch sizes produce poor [batch normalization](https://www.ultralytics.com/glossary/batch-normalization) statistics and should be avoided. You can use `--batch-size -1` to automatically select the optimal batch size for your GPU.
- **[Learning rate](https://www.ultralytics.com/glossary/learning-rate).** The default learning rate schedule works well in most cases. For faster convergence, you can try using the `--cos-lr` flag to enable cosine learning rate scheduling, which gradually reduces the learning rate following a cosine curve over epochs.
-- **[Data augmentation](https://www.ultralytics.com/glossary/data-augmentation).** YOLOv5 includes various augmentation techniques like mosaic, which combines multiple training images. For the last few epochs, consider using `--close-mosaic 10` to disable mosaic augmentation, which can help stabilize training.
+- **[Data augmentation](https://www.ultralytics.com/glossary/data-augmentation).** YOLOv5 includes various augmentation techniques like mosaic, which combines multiple training images. Adjust augmentation strength via the `mosaic` hyperparameter in your `--hyp` file to help stabilize training.
- **Hyperparameters.** Default hyperparameters are in [hyp.scratch-low.yaml](https://github.com/ultralytics/yolov5/blob/master/data/hyps/hyp.scratch-low.yaml). We recommend you train with default hyperparameters first before thinking of modifying any. In general, increasing augmentation hyperparameters will reduce and delay overfitting, allowing for longer trainings and higher final mAP. Reduction in loss component gain hyperparameters like `hyp['obj']` will help reduce overfitting in those specific loss components. For an automated method of optimizing these hyperparameters, see our [Hyperparameter Evolution Tutorial](./hyperparameter_evolution.md).
-- **[Mixed precision](https://www.ultralytics.com/glossary/mixed-precision) training.** Enable mixed precision training with `--amp` to speed up training and reduce memory usage without sacrificing model accuracy.
+- **[Mixed precision](https://www.ultralytics.com/glossary/mixed-precision) training.** YOLOv5 enables Automatic Mixed Precision (AMP) automatically when a supported GPU is detected, speeding up training and reducing memory usage without sacrificing model accuracy.
- **Multi-GPU training.** If you have multiple GPUs, use `--device 0,1,2,3` to distribute training across them, which can significantly reduce training time.
- **Early stopping.** Use `--patience 50` to stop training if validation metrics don't improve for 50 epochs, saving time and preventing overfitting.
@@ -93,4 +93,4 @@ The optimal batch size depends on your GPU memory. Larger batch sizes generally
### How can I speed up YOLOv5 training?
-To speed up training, try: enabling mixed precision training with `--amp`, using multiple GPUs with `--device 0,1,2,3`, caching your dataset with `--cache`, and optimizing your batch size. Also consider using a smaller model variant like YOLOv5s if absolute accuracy isn't critical.
+To speed up training, try: using multiple GPUs with `--device 0,1,2,3`, caching your dataset with `--cache`, and optimizing your batch size (mixed precision is enabled automatically on supported GPUs). Also consider using a smaller model variant like YOLOv5s if absolute accuracy isn't critical.
diff --git a/docs/en/yolov5/tutorials/train_custom_data.md b/docs/en/yolov5/tutorials/train_custom_data.md
index ef1d79b3..cdb8a7da 100644
--- a/docs/en/yolov5/tutorials/train_custom_data.md
+++ b/docs/en/yolov5/tutorials/train_custom_data.md
@@ -167,7 +167,7 @@ python train.py --img 640 --batch 16 --epochs 3 --data coco128.yaml --weights yo
💡 Always train using datasets stored locally. Accessing data from network drives (like Google Drive) or remote storage can be significantly slower and impede training performance. Copying your dataset to a local SSD is often the best practice.
-All training outputs, including weights and logs, are saved in the `runs/train/` directory. Each training session creates a new subdirectory (e.g., `runs/train/exp`, `runs/train/exp-2`, etc.). For an interactive, hands-on experience, explore the training section in our official tutorial notebooks: 
 +All training outputs, including weights and logs, are saved in the `runs/train/` directory. Each training session creates a new subdirectory (e.g., `runs/train/exp`, `runs/train/exp2`, etc.). For an interactive, hands-on experience, explore the training section in our official tutorial notebooks:
## 4. Visualize
diff --git a/docs/en/yolov5/tutorials/transfer_learning_with_frozen_layers.md b/docs/en/yolov5/tutorials/transfer_learning_with_frozen_layers.md
index 6e033ffa..1120208d 100644
--- a/docs/en/yolov5/tutorials/transfer_learning_with_frozen_layers.md
+++ b/docs/en/yolov5/tutorials/transfer_learning_with_frozen_layers.md
@@ -113,7 +113,7 @@ To illustrate the effects of freezing layers, we trained YOLOv5m on the [Pascal
```bash
# Example command for training with backbone frozen
-python train.py --batch 48 --weights yolov5m.pt --data voc.yaml --epochs 50 --cache --img 512 --hyp hyp.finetune.yaml --freeze 10
+python train.py --batch 48 --weights yolov5m.pt --data voc.yaml --epochs 50 --cache --img 512 --hyp data/hyps/hyp.VOC.yaml --freeze 10
```
### Accuracy Results
diff --git a/examples/README.md b/examples/README.md
index ed91eb9b..5fc2c59c 100644
--- a/examples/README.md
+++ b/examples/README.md
@@ -3,7 +3,7 @@
# Ultralytics YOLO Examples
> [!WARNING]
-> The examples in this directory are community-contributed and showcase creative ways to use Ultralytics YOLO models. While we truly appreciate these contributions, they may not always reflect the latest best practices or receive regular updates. To help streamline our codebase and focus our resources on maintaining comprehensive, up-to-date official documentation and guides, we plan to retire these examples in **Ultralytics v8.4.0**.
+> The examples in this directory are community-contributed and showcase creative ways to use Ultralytics YOLO models. While we truly appreciate these contributions, they may not always reflect the latest best practices or receive regular updates. To help streamline our codebase and focus our resources on maintaining comprehensive, up-to-date official documentation and guides, we plan to retire these examples in a future Ultralytics release.
Welcome to the Ultralytics examples directory! This collection showcases practical applications and detailed walkthroughs for integrating [Ultralytics YOLO models](https://docs.ultralytics.com/models) into various real-world projects. Explore Python scripts and Jupyter notebooks designed to help you leverage the power of models like [Ultralytics YOLO26](https://docs.ultralytics.com/models/yolo26) for tasks like [object detection](https://docs.ultralytics.com/tasks/detect), [instance segmentation](https://docs.ultralytics.com/tasks/segment), [semantic segmentation](https://docs.ultralytics.com/tasks/semantic), [pose estimation](https://docs.ultralytics.com/tasks/pose), and more.
diff --git a/examples/YOLOv8-CPP-Inference/README.md b/examples/YOLOv8-CPP-Inference/README.md
index 86571b8d..72ec82c9 100644
--- a/examples/YOLOv8-CPP-Inference/README.md
+++ b/examples/YOLOv8-CPP-Inference/README.md
@@ -53,10 +53,10 @@ yolo export model=yolov8s.pt imgsz=640,480 format=onnx opset=12 # Example: 640x4
**Exporting YOLOv5 Models:**
-Use the `export.py` script from the YOLOv5 repository structure (included within the cloned `ultralytics` repo).
+Use the `export.py` script from the separate [YOLOv5 repository](https://github.com/ultralytics/yolov5).
```bash
-# Assuming you are in the 'ultralytics' base directory after cloning
+# Run from the root of the cloned yolov5 repository
python export.py --weights yolov5s.pt --imgsz 640 480 --include onnx --opset 12 # Example: 640x480 resolution
```
diff --git a/examples/YOLOv8-LibTorch-CPP-Inference/README.md b/examples/YOLOv8-LibTorch-CPP-Inference/README.md
index 9185d81f..652725aa 100644
--- a/examples/YOLOv8-LibTorch-CPP-Inference/README.md
+++ b/examples/YOLOv8-LibTorch-CPP-Inference/README.md
@@ -52,7 +52,7 @@ Follow these steps to run the C++ inference example:
```
5. **Run the Inference:**
- Execute the compiled binary. The application will load the exported YOLOv8 model and perform inference on a sample image (`zidane.jpg` included in the root `ultralytics` directory) or video.
+ Execute the compiled binary. The application will load the exported YOLOv8 model and perform inference on a sample image. Edit the image path in `main.cc` (it defaults to a placeholder `/path/to/bus.jpg`) before running.
```bash
./yolov8_libtorch_inference
```
diff --git a/examples/YOLOv8-ONNXRuntime/README.md b/examples/YOLOv8-ONNXRuntime/README.md
index fd5eb457..ddaa17bb 100644
--- a/examples/YOLOv8-ONNXRuntime/README.md
+++ b/examples/YOLOv8-ONNXRuntime/README.md
@@ -63,7 +63,7 @@ python main.py --model yolov8n.onnx --img image.jpg --conf-thres 0.5 --iou-thres
- `--conf-thres`: Confidence threshold for filtering detections. Only detections with a score higher than this value will be kept. Learn more about thresholds in the [performance metrics guide](https://docs.ultralytics.com/guides/yolo-performance-metrics).
- `--iou-thres`: IoU threshold for Non-Maximum Suppression (NMS). Boxes with IoU greater than this threshold will be suppressed. See the [NMS glossary entry](https://www.ultralytics.com/glossary/non-maximum-suppression-nms) for details.
-The script will process the image, perform object detection, draw bounding boxes on the detected objects, and save the output image as `output.jpg`.
+The script will process the image, perform object detection, draw bounding boxes on the detected objects, and display the result in a window.
## Contributing
diff --git a/examples/YOLOv8-SAHI-Inference-Video/README.md b/examples/YOLOv8-SAHI-Inference-Video/README.md
index 7b76d420..b9f7d067 100644
--- a/examples/YOLOv8-SAHI-Inference-Video/README.md
+++ b/examples/YOLOv8-SAHI-Inference-Video/README.md
@@ -53,8 +53,8 @@ The script `yolov8_sahi.py` accepts several command-line arguments to customize
- `--source`: **Required**. Path to the input video file (e.g., `"../path/to/video.mp4"`).
- `--weights`: Optional. Path to the YOLO11 model weights file (e.g., `"yolo11n.pt"`, `"yolo11s.pt"`). Defaults to `"yolo11n.pt"`. You can download various models or use your custom-trained ones. See [Ultralytics YOLO models](https://docs.ultralytics.com/models) for more options.
- `--save-img`: Optional. Flag to export annotated frames. Saved to `runs/detect/predict`.
-- `--slice-height`: Optional. Height of each image slice for SAHI. Defaults to `1024`.
-- `--slice-width`: Optional. Width of each image slice for SAHI. Defaults to `1024`.
+- `--slice-height`: Optional. Height of each image slice for SAHI. Defaults to `512`.
+- `--slice-width`: Optional. Width of each image slice for SAHI. Defaults to `512`.
Experiment with these options, especially slice dimensions, to optimize detection performance for your specific [video processing](https://en.wikipedia.org/wiki/Video_processing) task and target object sizes. Using appropriate [datasets](https://docs.ultralytics.com/datasets) for training can also significantly impact performance.
diff --git a/ultralytics/cfg/__init__.py b/ultralytics/cfg/__init__.py
index 08a8fdee..be22b9b9 100644
--- a/ultralytics/cfg/__init__.py
+++ b/ultralytics/cfg/__init__.py
@@ -363,12 +363,12 @@ def check_cfg(cfg: dict, hard: bool = True) -> None:
>>> config = {
... "epochs": 50, # valid integer
... "lr0": 0.01, # valid float
- ... "momentum": 1.2, # invalid float (out of 0.0-1.0 range)
+ ... "momentum": 0.937, # valid float
... "save": "true", # invalid bool
... }
>>> check_cfg(config, hard=False)
>>> print(config)
- {'epochs': 50, 'lr0': 0.01, 'momentum': 1.2, 'save': False} # corrected 'save' key
+ {'epochs': 50, 'lr0': 0.01, 'momentum': 0.937, 'save': True} # corrected 'save' key
Notes:
- The function modifies the input dictionary in-place.
@@ -703,7 +703,7 @@ def handle_yolo_solutions(args: list[str]) -> None:
- Arguments can be provided in the format 'key=value' or as boolean flags
- Available solutions are defined in SOLUTION_MAP with their respective classes and methods
- If an invalid solution is provided, defaults to 'count' solution
- - Output videos are saved in 'runs/solution/{solution_name}' directory
+ - Output videos are saved in 'runs/solutions/exp' directory
- For 'analytics' solution, frame numbers are tracked for generating analytical graphs
- Video processing can be interrupted by pressing 'q'
- Processes video frames sequentially and saves output in .avi format
@@ -771,7 +771,7 @@ def handle_yolo_solutions(args: list[str]) -> None:
w, h, fps = (
int(cap.get(x)) for x in (cv2.CAP_PROP_FRAME_WIDTH, cv2.CAP_PROP_FRAME_HEIGHT, cv2.CAP_PROP_FPS)
)
- if solution_name == "analytics": # analytical graphs follow fixed shape for output i.e w=1920, h=1080
+ if solution_name == "analytics": # analytical graphs follow fixed shape for output i.e w=1280, h=720
w, h = 1280, 720
save_dir = get_save_dir(SimpleNamespace(task="solutions", name="exp", exist_ok=False, project=None))
save_dir.mkdir(parents=True, exist_ok=True) # create the output directory i.e. runs/solutions/exp
diff --git a/ultralytics/cfg/datasets/DOTAv1.5.yaml b/ultralytics/cfg/datasets/DOTAv1.5.yaml
index 4ac30830..b4a658dc 100644
--- a/ultralytics/cfg/datasets/DOTAv1.5.yaml
+++ b/ultralytics/cfg/datasets/DOTAv1.5.yaml
@@ -6,7 +6,7 @@
# parent
# ├── ultralytics
# └── datasets
-# └── dota1.5 ← downloads here (2 GB)
+# └── DOTAv1.5 ← downloads here (2 GB)
# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: DOTAv1.5 # dataset root dir
diff --git a/ultralytics/cfg/datasets/DOTAv1.yaml b/ultralytics/cfg/datasets/DOTAv1.yaml
index 6565b843..4d4f0bd7 100644
--- a/ultralytics/cfg/datasets/DOTAv1.yaml
+++ b/ultralytics/cfg/datasets/DOTAv1.yaml
@@ -6,7 +6,7 @@
# parent
# ├── ultralytics
# └── datasets
-# └── dota1 ← downloads here (2 GB)
+# └── DOTAv1 ← downloads here (2 GB)
# Train/val/test sets as 1) dir: path/to/imgs, 2) file: path/to/imgs.txt, or 3) list: [path/to/imgs1, path/to/imgs2, ..]
path: DOTAv1 # dataset root dir
diff --git a/ultralytics/data/augment.py b/ultralytics/data/augment.py
index bf203855..d15406bc 100644
--- a/ultralytics/data/augment.py
+++ b/ultralytics/data/augment.py
@@ -1455,7 +1455,7 @@ class RandomHSV(BaseTransform):
>>> augmented_img = labels["img"]
"""
img = labels["img"]
- if img.shape[-1] != 3: # only apply to RGB images
+ if img.shape[-1] != 3: # only apply to 3-channel (BGR) images
return labels
if self.hgain or self.sgain or self.vgain:
dtype = img.dtype # uint8
diff --git a/ultralytics/data/loaders.py b/ultralytics/data/loaders.py
index 0e791912..7278889c 100644
--- a/ultralytics/data/loaders.py
+++ b/ultralytics/data/loaders.py
@@ -33,7 +33,7 @@ class SourceTypes:
Attributes:
stream (bool): Flag indicating if the input source is a video stream.
screenshot (bool): Flag indicating if the input source is a screenshot.
- from_img (bool): Flag indicating if the input source is an image file.
+ from_img (bool): Flag indicating if the input source is an in-memory image (PIL/numpy) or list of images.
tensor (bool): Flag indicating if the input source is a tensor.
Examples:
@@ -153,7 +153,7 @@ class LoadStreams:
def update(self, i: int, cap: cv2.VideoCapture, stream: str):
"""Read stream frames in daemon thread and update image buffer."""
- n, f = 0, self.frames[i] # frame number, frame array
+ n, f = 0, self.frames[i] # frame number, total frames
while self.running and cap.isOpened() and n < (f - 1):
if len(self.imgs[i]) < 30: # keep a <=30-image buffer
n += 1
diff --git a/ultralytics/engine/exporter.py b/ultralytics/engine/exporter.py
index 295c76ad..ad06ecaa 100644
--- a/ultralytics/engine/exporter.py
+++ b/ultralytics/engine/exporter.py
@@ -435,10 +435,10 @@ class Exporter:
export_deepx: Export model to DEEPX format.
Examples:
- Export a YOLO26 model to ONNX format
+ Export a YOLO26 model to TorchScript format
>>> from ultralytics.engine.exporter import Exporter
>>> exporter = Exporter()
- >>> exporter(model="yolo26n.pt") # exports to yolo26n.onnx
+ >>> exporter(model="yolo26n.pt") # exports to yolo26n.torchscript
Export with specific arguments
>>> args = {"format": "onnx", "dynamic": True, "int8": True, "data": "coco8.yaml"}
diff --git a/ultralytics/engine/results.py b/ultralytics/engine/results.py
index 4c1cbb8e..00dc7542 100644
--- a/ultralytics/engine/results.py
+++ b/ultralytics/engine/results.py
@@ -331,7 +331,7 @@ class Results(SimpleClass, DataExportMixin):
masks (torch.Tensor | None): A tensor of shape (N, H, W) containing segmentation masks.
probs (torch.Tensor | None): A tensor of shape (num_classes,) containing class probabilities.
obb (torch.Tensor | None): A tensor of shape (N, 7) or (N, 8) containing oriented bounding box coordinates.
- keypoints (torch.Tensor | None): A tensor of shape (N, K, 3) containing keypoints, were K=17 for persons.
+ keypoints (torch.Tensor | None): A tensor of shape (N, K, 3) containing keypoints, where K=17 for persons.
semantic_mask (torch.Tensor | None): A tensor of shape (H, W) containing class IDs for semantic
segmentation.
@@ -507,7 +507,7 @@ class Results(SimpleClass, DataExportMixin):
Examples:
>>> results = model("image.jpg")
>>> for result in results:
- ... im = result.plot()
+ ... im = result.plot(pil=True)
... im.show()
"""
assert color_mode in {"instance", "class"}, f"Expected color_mode='instance' or 'class', not {color_mode}."
@@ -1505,7 +1505,7 @@ class OBB(BaseTensor):
bounding box. Returns None if tracking IDs are not available.
Examples:
- >>> results = model("image.jpg", tracker=True) # Run inference with tracking
+ >>> results = model.track("path/to/video.mp4") # Run inference with tracking
>>> for result in results:
... if result.obb is not None:
... track_ids = result.obb.id
diff --git a/ultralytics/models/nas/model.py b/ultralytics/models/nas/model.py
index 413b1595..7f42ec5e 100644
--- a/ultralytics/models/nas/model.py
+++ b/ultralytics/models/nas/model.py
@@ -80,7 +80,7 @@ class NAS(Model):
self.model.args = {**DEFAULT_CFG_DICT, **self.overrides} # for export()
self.model.eval()
- def info(self, detailed: bool = False, verbose: bool = True) -> dict[str, Any]:
+ def info(self, detailed: bool = False, verbose: bool = True) -> tuple:
"""Log model information.
Args:
diff --git a/ultralytics/models/rtdetr/val.py b/ultralytics/models/rtdetr/val.py
index b07e739d..15093e2b 100644
--- a/ultralytics/models/rtdetr/val.py
+++ b/ultralytics/models/rtdetr/val.py
@@ -16,7 +16,7 @@ __all__ = ("RTDETRValidator",) # tuple or list
class RTDETRDataset(YOLODataset):
- """Real-Time DEtection and TRacking (RT-DETR) dataset class extending the base YOLODataset class.
+ """Real-Time DEtection TRansformer (RT-DETR) dataset class extending the base YOLODataset class.
This specialized dataset class is designed for use with the RT-DETR object detection model and is optimized for
real-time detection and tracking tasks.
@@ -41,7 +41,7 @@ class RTDETRDataset(YOLODataset):
def __init__(self, *args, data=None, **kwargs):
"""Initialize the RTDETRDataset class by inheriting from the YOLODataset class.
- This constructor sets up a dataset specifically optimized for the RT-DETR (Real-Time DEtection and TRacking)
+ This constructor sets up a dataset specifically optimized for the RT-DETR (Real-Time DEtection TRansformer)
model, building upon the base YOLODataset functionality.
Args:
diff --git a/ultralytics/models/sam/predict.py b/ultralytics/models/sam/predict.py
index 2195c0df..9b123e35 100644
--- a/ultralytics/models/sam/predict.py
+++ b/ultralytics/models/sam/predict.py
@@ -228,7 +228,7 @@ class Predictor(BasePredictor):
>>> predictor = Predictor()
>>> im = torch.rand(1, 3, 1024, 1024)
>>> bboxes = [[100, 100, 200, 200]]
- >>> masks, scores, logits = predictor.prompt_inference(im, bboxes=bboxes)
+ >>> masks, scores = predictor.prompt_inference(im, bboxes=bboxes)
"""
features = self.get_im_features(im) if self.features is None else self.features
diff --git a/ultralytics/models/yolo/detect/train.py b/ultralytics/models/yolo/detect/train.py
index 2a1e81bb..94e19b64 100644
--- a/ultralytics/models/yolo/detect/train.py
+++ b/ultralytics/models/yolo/detect/train.py
@@ -152,7 +152,7 @@ class DetectionTrainer(BaseTrainer):
"""Compute and set class weights for handling class imbalance.
Class weights are computed based on inverse class frequency in the training dataset,
- raised to the power of cls_pw (0 < cls_pw <= 1 dampens, cls_pw > 1 amplifies).
+ raised to the power of cls_pw (0 < cls_pw <= 1 dampens; values are restricted to the range [0, 1]).
Final weights are normalized so their mean equals 1.0.
"""
assert 0 <= self.args.cls_pw <= 1.0, "cls_pw must be in the range [0, 1]"
diff --git a/ultralytics/models/yolo/detect/val.py b/ultralytics/models/yolo/detect/val.py
index 7d420cda..5cf2a8cc 100644
--- a/ultralytics/models/yolo/detect/val.py
+++ b/ultralytics/models/yolo/detect/val.py
@@ -31,7 +31,6 @@ class DetectionValidator(BaseValidator):
metrics (DetMetrics): Object detection metrics calculator.
iouv (torch.Tensor): IoU thresholds for mAP calculation.
niou (int): Number of IoU thresholds.
- lb (list[Any]): List for storing ground truth labels for hybrid saving.
jdict (list[dict[str, Any]]): List for storing JSON detection results.
stats (dict[str, list[torch.Tensor]]): Dictionary for storing statistics during validation.
diff --git a/ultralytics/models/yolo/model.py b/ultralytics/models/yolo/model.py
index 6cce8d7f..386dcf98 100644
--- a/ultralytics/models/yolo/model.py
+++ b/ultralytics/models/yolo/model.py
@@ -220,7 +220,7 @@ class YOLOE(Model):
predict: Run prediction on images, videos, directories, streams, etc.
Examples:
- Load a YOLOE detection model
+ Load a YOLOE segmentation model
>>> model = YOLOE("yoloe-11s-seg.pt")
Set vocabulary and class names
diff --git a/ultralytics/models/yolo/pose/val.py b/ultralytics/models/yolo/pose/val.py
index 02b8d3a7..aea4164f 100644
--- a/ultralytics/models/yolo/pose/val.py
+++ b/ultralytics/models/yolo/pose/val.py
@@ -140,11 +140,11 @@ class PoseValidator(DetectionValidator):
batch (dict[str, Any]): Dictionary containing batch data with keys like 'keypoints', 'batch_idx', etc.
Returns:
- (dict[str, Any]): Prepared batch with keypoints scaled to original image dimensions.
+ (dict[str, Any]): Prepared batch with keypoints scaled to model input (letterboxed) image dimensions.
Notes:
This method extends the parent class's _prepare_batch method by adding keypoint processing.
- Keypoints are scaled from normalized coordinates to original image dimensions.
+ Keypoints are scaled from normalized coordinates to the model input (letterboxed) image dimensions.
"""
pbatch = super()._prepare_batch(si, batch)
kpts = batch["keypoints"][batch["batch_idx"] == si]
diff --git a/ultralytics/models/yolo/segment/val.py b/ultralytics/models/yolo/segment/val.py
index 386b7cbf..d159079e 100644
--- a/ultralytics/models/yolo/segment/val.py
+++ b/ultralytics/models/yolo/segment/val.py
@@ -22,7 +22,6 @@ class SegmentationValidator(DetectionValidator):
compute metrics such as mAP for both detection and segmentation tasks.
Attributes:
- plot_masks (list): List to store masks for plotting.
process (callable): Function to process masks based on save_json and save_txt flags.
args (SimpleNamespace): Arguments for the validator.
metrics (SegmentMetrics): Metrics calculator for segmentation tasks.
diff --git a/ultralytics/nn/modules/head.py b/ultralytics/nn/modules/head.py
index cb81a0b1..e01eeb04 100644
--- a/ultralytics/nn/modules/head.py
+++ b/ultralytics/nn/modules/head.py
@@ -98,7 +98,7 @@ class Detect(nn.Module):
super().__init__()
self.nc = nc # number of classes
self.nl = len(ch) # number of detection layers
- self.reg_max = reg_max # DFL channels (ch[0] // 16 to scale 4/8/12/16/20 for n/s/m/l/x)
+ self.reg_max = reg_max # DFL channels
self.no = nc + self.reg_max * 4 # number of outputs per anchor
self.stride = torch.zeros(self.nl) # strides computed during build
c2, c3 = max((16, ch[0] // 4, self.reg_max * 4)), max(ch[0], min(self.nc, 100)) # channels
@@ -997,7 +997,7 @@ class YOLOEDetect(Detect):
>>> yoloe_detect = YOLOEDetect(nc=80, embed=512, with_bn=True, ch=(256, 512, 1024))
>>> x = [torch.randn(1, 256, 80, 80), torch.randn(1, 512, 40, 40), torch.randn(1, 1024, 20, 20)]
>>> cls_pe = torch.randn(1, 80, 512)
- >>> outputs = yoloe_detect(x, cls_pe)
+ >>> outputs = yoloe_detect([*x, cls_pe])
"""
is_fused = False
@@ -1207,7 +1207,7 @@ class YOLOESegment(YOLOEDetect):
>>> yoloe_segment = YOLOESegment(nc=80, nm=32, npr=256, embed=512, with_bn=True, ch=(256, 512, 1024))
>>> x = [torch.randn(1, 256, 80, 80), torch.randn(1, 512, 40, 40), torch.randn(1, 1024, 20, 20)]
>>> text = torch.randn(1, 80, 512)
- >>> outputs = yoloe_segment(x, text)
+ >>> outputs = yoloe_segment([*x, text])
"""
def __init__(
@@ -1854,8 +1854,9 @@ class SemanticSegment(nn.Module):
x (list[torch.Tensor]): List of feature maps [P3, P4].
Returns:
- (torch.Tensor): Logits of shape [B, nc, H/8, W/8] during training, inference, and CoreML export. Other
- export formats return upsampled logits of shape [B, nc, H, W].
+ (torch.Tensor | tuple): Logits of shape [B, nc, H/8, W/8] during training (or a (main, aux) tuple when
+ aux_head is present), inference, and CoreML export. Other export formats return upsampled logits of
+ shape [B, nc, H, W].
"""
# Classify
logits = self.classifier(x[0]) # [B, nc, H/8, W/8]
diff --git a/ultralytics/solutions/instance_segmentation.py b/ultralytics/solutions/instance_segmentation.py
index 2f90e0fd..2457321f 100644
--- a/ultralytics/solutions/instance_segmentation.py
+++ b/ultralytics/solutions/instance_segmentation.py
@@ -13,7 +13,7 @@ class InstanceSegmentation(BaseSolution):
drawing segmented masks with bounding boxes and labels.
Attributes:
- model (str): The segmentation model to use for inference.
+ model (YOLO): The segmentation model instance used for inference.
line_width (int): Width of the bounding box and text lines.
names (dict[int, str]): Dictionary mapping class indices to class names.
clss (list[int]): List of detected class indices.
diff --git a/ultralytics/solutions/object_counter.py b/ultralytics/solutions/object_counter.py
index 6f7a5b78..940c7a2f 100644
--- a/ultralytics/solutions/object_counter.py
+++ b/ultralytics/solutions/object_counter.py
@@ -144,9 +144,9 @@ class ObjectCounter(BaseSolution):
im0 (np.ndarray): The input image or frame to be processed.
Returns:
- (SolutionResults): Contains processed image `im0`, 'in_count' (int, count of objects entering the region),
- 'out_count' (int, count of objects exiting the region), 'classwise_count' (dict, per-class object
- count), and 'total_tracks' (int, total number of tracked objects).
+ (SolutionResults): Contains processed image `plot_im`, 'in_count' (int, count of objects entering the
+ region), 'out_count' (int, count of objects exiting the region), 'classwise_count' (dict, per-class
+ object count), and 'total_tracks' (int, total number of tracked objects).
Examples:
>>> counter = ObjectCounter()
diff --git a/ultralytics/solutions/queue_management.py b/ultralytics/solutions/queue_management.py
index f55021ae..ec515354 100644
--- a/ultralytics/solutions/queue_management.py
+++ b/ultralytics/solutions/queue_management.py
@@ -51,8 +51,8 @@ class QueueManager(BaseSolution):
im0 (np.ndarray): Input image for processing, typically a frame from a video stream.
Returns:
- (SolutionResults): Contains processed image `im0`, 'queue_count' (int, number of objects in the queue) and
- 'total_tracks' (int, total number of tracked objects).
+ (SolutionResults): Contains processed image `plot_im`, 'queue_count' (int, number of objects in the queue)
+ and 'total_tracks' (int, total number of tracked objects).
Examples:
>>> queue_manager = QueueManager()
diff --git a/ultralytics/utils/autobatch.py b/ultralytics/utils/autobatch.py
index f6c2f69a..abcb227d 100644
--- a/ultralytics/utils/autobatch.py
+++ b/ultralytics/utils/autobatch.py
@@ -109,7 +109,7 @@ def autobatch(
and (i == 0 or not results[i - 1] or y[2] > results[i - 1][2]) # first item or increasing memory
]
fit_x, fit_y = zip(*xy) if xy else ([], [])
- p = np.polyfit(fit_x, fit_y, deg=1) # first-degree polynomial fit in log space
+ p = np.polyfit(fit_x, fit_y, deg=1) # first-degree (linear) polynomial fit
b = int((round(f * fraction) - p[1]) / p[0]) # y intercept (optimal batch size)
if None in results: # some sizes failed
i = results.index(None) # first fail index
diff --git a/ultralytics/utils/loss.py b/ultralytics/utils/loss.py
index 88b97cf1..9620b34b 100644
--- a/ultralytics/utils/loss.py
+++ b/ultralytics/utils/loss.py
@@ -1050,7 +1050,7 @@ class v8OBBLoss(v8DetectionLoss):
) from e
# Pboxes
- pred_bboxes = self.bbox_decode(anchor_points, pred_distri, pred_angle) # xyxy, (b, h*w, 4)
+ pred_bboxes = self.bbox_decode(anchor_points, pred_distri, pred_angle) # xywhr, (b, h*w, 5)
bboxes_for_assigner = pred_bboxes.clone().detach()
# Only the first four elements need to be scaled
diff --git a/ultralytics/utils/metrics.py b/ultralytics/utils/metrics.py
index b7e227f7..fc3e926e 100644
--- a/ultralytics/utils/metrics.py
+++ b/ultralytics/utils/metrics.py
@@ -333,7 +333,7 @@ class ConfusionMatrix(DataExportMixin):
"""A class for calculating and updating a confusion matrix for object detection and classification tasks.
Attributes:
- task (str): The type of task, either 'detect' or 'classify'.
+ task (str): The type of task, one of 'detect', 'classify', 'semantic', or 'obb'.
matrix (np.ndarray): The confusion matrix, with dimensions depending on the task.
nc (int): The number of classes.
names (dict[int, str]): The names of the classes, used as labels on the plot.
@@ -345,7 +345,7 @@ class ConfusionMatrix(DataExportMixin):
Args:
names (dict[int, str], optional): Names of classes, used as labels on the plot.
- task (str, optional): Type of task, either 'detect' or 'classify'.
+ task (str, optional): Type of task, one of 'detect', 'classify', 'semantic', or 'obb'.
save_matches (bool, optional): Save the indices of GTs, TPs, FPs, FNs for visualization.
"""
self.task = task
diff --git a/ultralytics/utils/ops.py b/ultralytics/utils/ops.py
index f8035bb7..03cbf07a 100644
--- a/ultralytics/utils/ops.py
+++ b/ultralytics/utils/ops.py
@@ -142,14 +142,14 @@ def scale_boxes(
def make_divisible(x: int, divisor):
- """Return the nearest number that is divisible by the given divisor.
+ """Return the smallest number >= x that is divisible by the given divisor.
Args:
x (int): The number to make divisible.
divisor (int | torch.Tensor): The divisor.
Returns:
- (int): The nearest number divisible by the divisor.
+ (int): The smallest number >= x divisible by the divisor.
"""
if isinstance(divisor, torch.Tensor):
divisor = int(divisor.max()) # to int
@@ -495,8 +495,8 @@ def process_mask(protos, masks_in, bboxes, shape, upsample: bool = False):
upsample (bool): Whether to upsample masks to original image size.
Returns:
- (torch.Tensor): A binary mask tensor of shape [n, h, w], where n is the number of masks after NMS, and h and w
- are the height and width of the input image. The mask is applied to the bounding boxes.
+ (torch.Tensor): A binary mask tensor of shape [n, h, w], where n is the number of masks after NMS. When
+ upsample=True h and w match the input image size; otherwise they are the prototype mask resolution.
"""
c, mh, mw = protos.shape # CHW
masks = (masks_in @ protos.float().view(c, -1)).view(-1, mh, mw) # NHW
diff --git a/ultralytics/utils/plotting.py b/ultralytics/utils/plotting.py
index 8975da65..80f1046b 100644
--- a/ultralytics/utils/plotting.py
+++ b/ultralytics/utils/plotting.py
@@ -92,7 +92,7 @@ class Colors:
"""
def __init__(self):
- """Initialize colors as hex = matplotlib.colors.TABLEAU_COLORS.values()."""
+ """Initialize the Ultralytics color palette from a fixed list of hex color codes."""
hexs = (
"042AFF",
"0BDBEB",